A private ChatGPT for fifty teams, and one bill you can split
How one private AI assistant serves fifty teams through one address, and how its fixed hourly cost becomes a bill per team. A demo, with its limits.
How one private AI assistant serves fifty teams through one address, and how its fixed hourly cost becomes a bill per team. A demo, with its limits.
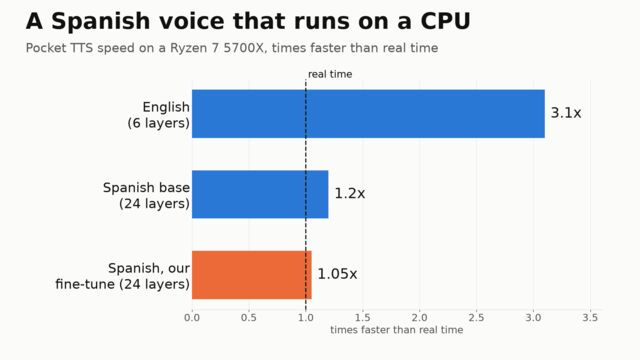
We fine-tuned Kyutai's Pocket TTS for Castilian Spanish. It runs on a plain CPU, with samples in Spanish, English, French and German.
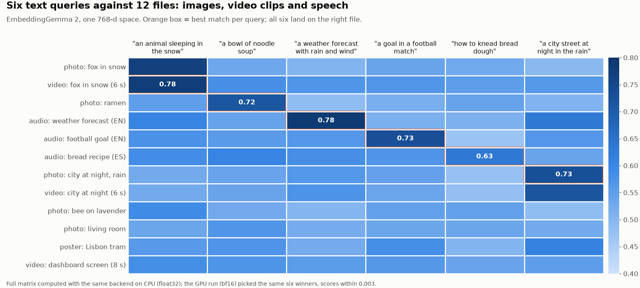
Google's EmbeddingGemma 2 puts text, images, video and audio in one search space. It loaded in 1.4 GB on our 16 GB RTX 2000 Ada.
Kandinsky 6.0 makes 5-second clips with synced audio under MIT. Minutes per clip on seven GPUs, and why every published run uses offload.
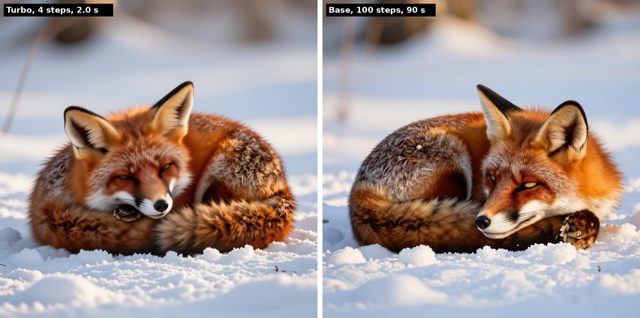
Iris-3B is an open image model that draws pixels itself. We ran its fast Turbo version on InferenceKey: about 2 seconds a picture on an A40.
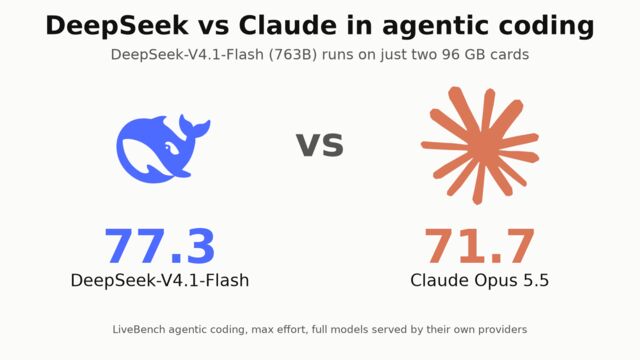
DeepSeek-V4.1-Flash, a 763B model, would take 1.5 TB in FP16. We run it on two 96 GB cards for 19 developers, thanks to open source.
BAAI's Apache-2.0 AREX-2 shares Qwen3.8-27B's architecture. What our base-model sglang runs say about its VRAM, quants and GPUs, and what is untested.
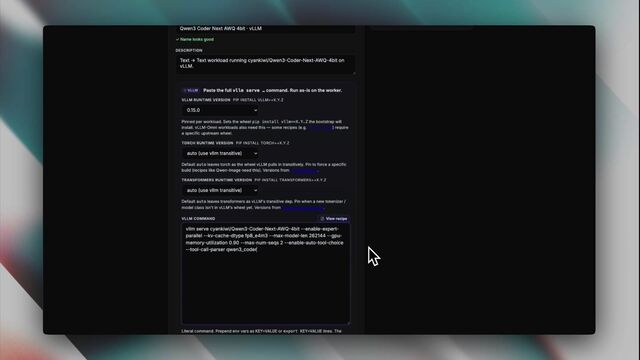
Qwen3 Coder Next (80B, AWQ 4-bit) on vLLM, one A100 80 GB at $1.79/h, an API key for one developer and Claude Code pointed at it. Commands, numbers, limits.